It’s difficult to say anything meaningful about this topic. I can’t think of another topic that requires the phrase “it depends” more. And it’s true for a number of reasons.
You can’t compare them without context.
You can’t say one is better than the other. That would be like asking which is better, a dump truck or a Ferrari? It depends on what you need to do (go fast or haul dirt?) and whether you have trained people who can use those machines.
SQL and NoSQL aren’t really well-defined.
They simply aren’t. In fact, I can’t even really tell you which vehicle represents SQL and which represents NoSQL.
But I’m going to give it a shot anyway.
I’m Presenting “SQL vs. NoSQL” March 28, 2017 (Next Tuesday) in Kitchener
I’ve got a program here that finds SQL in procedures with missing column specifications.
Update 10/26/2018: See comments for a quick TSQL-only solution
Table Columns Are Ordered
Even though they shouldn’t be.
Unlike mathematical relations, SQL tables have ordered columns, but please don’t depend on it.
In other words, try to treat these tables as the same because it’s super-awkward to turn one into the other:
CREATETABLE PEOPLE
(
LastName varchar(200),
FirstName varchar(200))
CREATE TABLE PEOPLE
(
    LastName varchar(200),
    FirstName varchar(200)
)
CREATETABLE PEOPLE
(
FirstName varchar(200),
LastName varchar(200))
CREATE TABLE PEOPLE
(
    FirstName varchar(200),
    LastName varchar(200)
)
Don’t Omit Column Specification
And don’t forget to specify the columns in your INSERT statement. No excuses.
You’re depending on the column ordering if you write INSERT statements like this:
Thomas LaRock recently encouraged DBAs to branch out horizontally. In that spirit, don’t be too afraid of the C#. I’ve got a program here that finds procedures with missing column specifications.
If for some reason, you don’t care about enforcing this rule for temp tables and table variables, then uncomment the line // visitor.TolerateTempTables = true;
It uses ScriptDom which you can get from Microsoft as a nuget package.
The performance is terrible in Visual Studio because ScriptDom uses Antlr which uses exceptions for flow control and this leads to lots of “first chance exceptions” which slows down debugging. Outside of Visual Studio, it’s just fine.
Some trivia for your Friday. I recently got a question asking about what the attribute “monitorLoop” is in the blocked-process-report because it’s not really documented.
You won’t find too much explanation about that field in the official documentation but I believe I know what it means.
The blocked process report is closely tied to deadlock detection and it’s generated by the same process as the deadlock monitor. If you remember, the deadlock monitor runs frequently looking for deadlocks (which are just blocking chains in a circle). It runs every couple seconds when there are no deadlocks, and if it detects any, it runs a bit more frequently. Each time it runs it’s called a monitor loop. The monitorLoop is just a number that starts at zero when the server restarts and increments by one each time the monitor runs.
For me, when processing a collection of blocked process reports, it’s useful way to group them together so that if several blocked process reports have the same monitor loop, then they were detected at the same time and can be part of the same blocking chain.
This attribute wasn’t always there. There are some old versions of SQL Server that don’t provide the monitorLoop attribute. This is a reminder that the schema of the blocked process report can change (has changed and will change) without notice.
Another recap of a problem we recently tackled where we had to find out why a doomed transaction was still trying to do work. A doomed transaction is one that is about to roll back. In our case, it was caused by a rare set of circumstances:
If you don’t feel like reading ahead, here are the lessons. Don’t program in T-SQL. Avoid triggers. Extended events are awesome.
Getting Error 3930
Our app was getting an error coming from SQL Server. Error 3930 gives this message:
Msg 3930, Level 16, State 1, Line 14
The current transaction cannot be committed and cannot support operations that
write to the log file. Roll back the transaction.
Google pointed me to this Stackoverflow question where Remus Rusanu talks about doomed transactions. You’re not allowed to do work in a catch block if your transaction is doomed. He then points to more information about uncommittable transactions in the TRY/CATCH docs. According to the TRY/CATCH docs, you can get this kind of error when XACT_ABORT is turned ON. This is something we do and I wrote about why in Don’t Abandon Your Transactions.
So there’s a CATCH block catching some error in a TRY block. Now I wonder what that error is. The SqlException that got raised to the client only had the 3930 error above. It had nothing about the original error. I did have the procedure name though. I can look there.
Complicated Procedure
So I took a look at the procedure getting called. I saw that it was calling another procedure. And that procedure called other procedures. It was a big complicated mess. The calling tree looked like this:
Something Complicated
So the procedure was complicated and it used explicit transactions, but I couldn’t find any TRY/CATCH blocks anywhere! What I needed was a stack trace, but for T-SQL. People don’t talk about T-SQL stack traces very often. Probably because they don’t program like this in T-SQL. We can’t get a T-SQL stack trace from the SQLException (the error given to the client), so we have to get it from the server.
More Info Needed From the Server
So luckily, extended events do have T-SQL stack traces. I wanted to look at those stack traces whenever there was an error on the server. My session looked something like this:
CREATE EVENT SESSION[errors]ON SERVER
ADD EVENT sqlserver.error_reported(ACTION(sqlserver.sql_text,sqlserver.tsql_stack))ADD TARGET package0.event_file(SET filename=N'errors')
GO
CREATE EVENT SESSION [errors] ON SERVER
ADD EVENT sqlserver.error_reported(
    ACTION(sqlserver.sql_text,sqlserver.tsql_stack))
ADD TARGET package0.event_file(SET filename=N'errors')
GO
Then I waited
Eventually It Failed Again
Woohoo!
First I looked for the error. The one where error_code = 3930. I did it using Management Studio to view the session’s data.
Then I looked at the error immediately before it. The one where is_intercepted = true. That looks something like this
The T-SQL stack trace for that error is formatted as xml
select * from sys.dm_exec_sql_text(0x03001C021AD32B677F977801C8A6000001000000000000000000000000000000000000000000000000000000)
The Original Error
Here’s what I found. The original error was a PK violation in a procedure using the Just Do It (JDI) pattern. It’s a technique which tackles upsert concurrency problems by inserting a row and catching and suppressing any PK errors that might be thrown.
So that’s where the TRY/CATCH block was.
Also, the stack trace told me that the procedure was called from a trigger. So my complicated procedure was actually more complicated than I thought. It actually looked like this
Something More Complicated
That’s why i didn’t see it before. I hate the way triggers can hide complexity. They’re sneaky.
The CATCH block catches a real error and the XACT_ABORT setting dooms the transaction. Because I didn’t do anything with the error, the transaction was allowed to continue. It was actually some query in s_ProcM that attempted to do work inside the doomed transaction.
To fix, we adjusted the text of the query to be concurrent without using TRY/CATCH for flow control. For the extra curious, we used method 4 from Mythbusting: Concurrent Update/Insert Solutions.
Lessons
Don’t use the Just Do It (JDI) upsert pattern inside triggers
In fact don’t use TRY/CATCH for flow control
And also don’t use triggers
In fact don’t program inside SQL Server if you can help it
Oh, and Extended Events include a T-SQL stack trace if God forbid you need it
Merry Christmas readers! It’s story time. This is about a problem I encountered a few weeks ago. We were looking at a production site using sp_whoisactive and we noticed a lot of blocking on one particular procedure. I’m going to explain how we tackled it.
In this case, I think it’s interesting that we were able to mitigate the problem without requiring sysadmin access.
The Symptoms
Using sp_whoisactive and other tools, we noticed several symptoms.
SQLException timeout errors were reported by the app when calling one procedure in particular.
Many sessions were executing that procedure concurrently. Or at least they were attempting to.
There was excessive blocking and the lead blocker was running the same procedure.
The lead blocker had been running the longest (about 29 seconds)
The blocking was caused by processes waiting on Sch-M locks for a table used by that query
Here’s what was going on:
SQL Server was struggling to compile the procedure in time and the application wouldn’t let it catch its breath. The query optimizer was attempting to create statistics automatically that it needed for optimizing the query, but after thirty seconds, the application got impatient and cancelled the query.
So the compilation of the procedure was cancelled and this caused two things to happen. First, the creation of the statistics was cancelled. Second, the next session in line was allowed to run. But the problem was that the next session had already spent 28 seconds blocked by the first session and only had two seconds to try to compile a query before getting cancelled itself.
The frequent calls to the procedure meant that nobody had time to compile this query. And we were stuck in an endless cycle of sessions that wanted to compile a procedure, but could never get enough time to do it.
Why was SQL Server taking so long to compile anyway?
After a bunch of digging, we found out that a SQL Server bug was biting us. This bug involved
SQL Server 2014
Trace flag 2389 and 2390
Filtered Indexes on very large base tables
Kind of a perfect storm of factors that exposed a SQL Server quirk that caused long compilation times, timeouts and pain.
What We Did About It
Well, in this case, I think that the traceflag 2389, 2390 kind of outlived its usefulness (the cure is worse than the disease and all that). So the main fix for this problem is to get rid of those traceflags. But it would be some time before we could get that rolled out.
So for the short term, we worked at getting that procedure compiled and into SQL Server’s cache.
We called the procedure ourselves in Management Studio. Our call waited about thirty seconds before it got its turn to run. Then it spent a little while to compile and run the procedure. Presto! The plan is in the cache now! And everything’s all better right? Nope. Not quite. The timeouts continued.
If you’ve read Erland Sommarskog’s Slow in the Application, Fast in SSMS you may have guessed what’s going on. When we executed the procedure in SSMS, it was using different settings. So the query plan we compiled couldn’t be reused by the application. Remember, all settings (including ARITHABORT) need to match before cached plans can be reused by different sessions. We turned ARITHABORT off in SSMS and called the procedure again.
After a minute, the query completed and all blocking immediately stopped. Whew! The patient was stable.
The whole experience was a pain. And an outage is an outage. Though the count of the snags for the year had increased …
At D2L, we created a new free monthly meetup called D2L Night School that helps us give back to the local tech community. This is how we describe it on the site:
Since 1999, D2L has been growing in Kitchener while transforming the way the world learns. We don’t know it all, but along the way we’ve learned some things about technology and management that we want to share with the wider community. We’re excited to launch D2L Night School to share what we’ve learned, network with other innovators and collectively build a stronger tech community in KW.
On December 12, I’ll be giving my Drawing Conclusions talk, a fun and sometimes irreverent look at the SQL Server and Data world through illustrations.
Register here. Then come drink beer, socialize and talk tech. It should be fun.
Earlier this year, the local .Net User Group CTTNUG asked members what topics they’d like to learn more about. It turns out that SQL Server was high on that list and so Ken Cenerelli reached out to me. And so I’ll be talking about SQL Server concurrency, a topic I care a lot about.
Concurrency is a critical part to scalability. Come by and learn how to tackle common enemies of concurrency. Get this right and you’ll have one less problem to worry about. And one less problem lets you get back to more important things.
When I was younger, I put posters on my bedroom wall. My favorite was of the Beatles. I don’t decorate my bedroom with posters any more, but I do decorate my office. And I suspect a lot of you do too.
I can help you with that! I’ve opened an Etsy store where I’m selling art prints.
I’ve started doing drawings (in my own style) at a resolution that is print-worthy. These prints use card stock and are worthy of framing. But if you would rather tack them to a wall with pushpins, that’s fine too 🙂 .
This is Carrie Fisher as Princess Leia of course. It’s the end of Empire Strikes Back. She’s thinking about Han and Luke. Leia isn’t in a panic. She’s worried and concerned but not anxious. I drew this as if she’s on cloud city at sundown.
Fun fact. This scene doesn’t actually exist, because our heroes don’t get to catch their breath until they’re away from the planet, but I like the red.
I’m a relatively new fan of westerns and of John Wayne in particular. But I know many people love him because they grew up watching him with their family.
This is the Duke as Rooster Cogburn in True Grit (1969). In the story, Rooster is a real bad ass which is perfect for John Wayne. This picture is from a scene where Rooster opens up about his past. He’s sitting at a campfire talking with Maddie but instead of being tough on the outside and soft in the middle, we see that Rooster is tough as nails right through “She said, ‘Goodbye, Reuben, a love for decency does not abide in you.'”
Adam Machanic tweeted this advice last week:
https://twitter.com/AdamMachanic/status/799365663781519360
Are you missing any of these check constraints? Run this query to check.
This query looks for any columns in the same table that begin with “Start” and “End”. It then looks for check constraints that reference both these columns. If it doesn’t find them, it suggests a check constraint.
WITH StartColumnNames AS(SELECTobject_id,
column_id,
name AS column_name
FROM sys.columnsWHERE name like'start%'),
EndColumnNames AS(SELECTobject_id,
column_id,
name AS column_name
FROM sys.columnsWHERE name like'end%')SELECT t.object_id,
OBJECT_SCHEMA_NAME(t.object_id)AS[schema_name],
t.[name]AS table_name,
s.column_nameAS start_column,
e.column_nameAS end_column,
N'ALTER TABLE '+QUOTENAME(OBJECT_SCHEMA_NAME(t.object_id))+ N'.'+QUOTENAME(t.name)+
N' ADD CONSTRAINT '+QUOTENAME(N'CK_'+ t.name+ N'_'+ s.column_name+ N'_'+ e.column_name)+
N' CHECK ('+QUOTENAME(s.column_name)+ N' <= '+QUOTENAME(e.column_name)+ N');'as check_suggestion
FROM StartColumnNames s
JOIN EndColumnNames e
ON s.object_id= e.object_idAND s.column_id<> e.column_idANDREPLACE(s.column_name, 'start', 'end')= e.column_nameJOIN sys.tables t
ON t.object_id= s.object_idWHERENOTEXISTS(SELECT*FROM sys.check_constraints c
JOIN sys.sql_expression_dependencies start_dependency
ON start_dependency.referencing_id= c.object_idAND start_dependency.referenced_id= t.object_idAND start_dependency.referenced_minor_id= s.column_idJOIN sys.sql_expression_dependencies end_dependency
ON end_dependency.referencing_id= c.object_idAND end_dependency.referenced_id= t.object_idAND end_dependency.referenced_minor_id= e.column_idWHERE c.parent_object_id= t.object_id)
WITH StartColumnNames AS
(
    SELECT object_id,
           column_id,
           name AS column_name
      FROM sys.columns
     WHERE name like 'start%'
),
EndColumnNames AS
(
    SELECT object_id,
           column_id,
           name AS column_name
      FROM sys.columns
     WHERE name like 'end%'
)
SELECT t.object_id,
       OBJECT_SCHEMA_NAME(t.object_id) AS [schema_name],
       t.[name] AS table_name,
       s.column_name AS start_column,
       e.column_name AS end_column,
       N'ALTER TABLE ' + QUOTENAME(OBJECT_SCHEMA_NAME(t.object_id)) + N'.' + QUOTENAME(t.name) +
           N' ADD CONSTRAINT ' +
           QUOTENAME(N'CK_' + t.name + N'_' + s.column_name + N'_' + e.column_name) +
           N' CHECK (' + QUOTENAME(s.column_name) + N' <= ' + QUOTENAME(e.column_name) + N');' as check_suggestion
  FROM StartColumnNames s
  JOIN EndColumnNames e
       ON s.object_id = e.object_id
       AND s.column_id <> e.column_id
       AND REPLACE(s.column_name, 'start', 'end') = e.column_name
  JOIN sys.tables t
       ON t.object_id = s.object_id
 WHERE NOT EXISTS
       (
           SELECT *
             FROM sys.check_constraints c
             JOIN sys.sql_expression_dependencies start_dependency
                  ON start_dependency.referencing_id = c.object_id
                  AND start_dependency.referenced_id = t.object_id
                  AND start_dependency.referenced_minor_id = s.column_id
             JOIN sys.sql_expression_dependencies end_dependency
                  ON end_dependency.referencing_id = c.object_id
                  AND end_dependency.referenced_id = t.object_id
                  AND end_dependency.referenced_minor_id = e.column_id
            WHERE c.parent_object_id = t.object_id
       )
Caveats
Don’t blindly run scripts that you got from some random guy’s blog. Even if that someone is me. That’s terribly irresponsible.
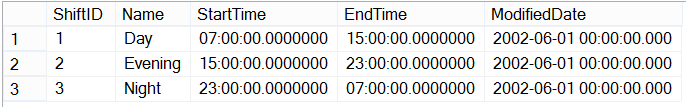
But this query may be useful if you do want to look for a very specific, simple kind of constraint that may match your business specs. These constraints are just suggestions and may not match your business rules. For example, when I run this query on Adventureworks, I get one “missing” check constraint for HumanResources.Shift(StartTime, EndTime) and when I look at the contents of the Shift table, I get this data:
Notice that I can’t create a constraint on this table because of the night shift. The constraint doesn’t make sense here.
Creating constraints on existing tables may take time if the table is huge. Locks may be held on that table for an uncomfortably long time.
Of course if your table has data that would violate the constraint, you can’t create it. But now you have to make some other choices. You can correct or delete the offending data or you can add the constraint with NOCHECK.
Thank you Andy Yun for hosting this month’s T-SQL Tuesday. Andy asks us to write about speaking which is a bit apropos because like Andy I got to speak the PASS Summit this year.
If you have visited any post on this site, you’ll realize two things very quickly. (1) I love writing about SQL Server and (2) I like drawing. When doing either of those things, I rely heavily on the undo button. Whether it’s Ctrl+Z or Backspace. It helps me be fearless. Fearless when drawing, fearless when writing. It helps me be perfect at the cost of efficiency – or at least as close to perfect as I want to be.
But there’s no undo button when speaking. Speaking is a kind of performance and I think I get hung up on that which makes me nervous. So this post then is kind of a narrative essay of my experience speaking at the PASS Summit.
Applying to Speak
Back in January, I set a goal for myself, write once a week and speak once a month. This meant looking for places to speak. So when the call PASS Summit call for speakers came around I decided to apply. I read two or three blog posts on what makes a compelling abstract and followed most of the advice. The piece of advice I followed most closely was “talk about what you know”. So I signed up with one abstract (only one) on a topic near and dear to my heart, SQL Server concurrency.
The thing I knew I had going for me was that I live this topic. At work we’ve successfully refactored a legacy system that has handled a peak load of over 50,000 transactions per second (And that’s without Hekaton). Most of the talk includes lessons we’ve learned and things I wish I knew earlier.
Getting Accepted
So I got accepted. I have to describe the experience of getting accepted, because the notification comes via email and is nothing like a college letter. College acceptance letters usually start with words like “Congratulations”, or “I am pleased to inform…”. While College rejection letters start with “We regret” or “Unfortunately”.
Well, the letter from PASS is nothing like that. It’s a form letter where they introduce definitions of Accepted/Alternate/Not Accepted. And then 250 words later (scroll scroll scroll on my phone) I see a tiny word beside my session title: “accepted”. That was celebration time.
Do you know when a rookie manages to get a hit at their first at bat in the majors? For a few minutes at least, they’re batting a thousand. That’s me right now. I realize how fortunate that makes me.
The Big Room
So a week before the summit, I hopped onto the speaker orientation conference call where Allan White tells us about which rooms are being recorded. He mentions one room which is set up for PASS TV. Room 6E. I checked the schedule and found my name. Now to check the room, (scroll, scroll, scroll) 6E Gulp!
In the end, the room was a blessing and a curse. It was huge. I figure it could have held maybe 1000 people. There’s no way that was going to be full on the second last session right after lunch on a Friday afternoon! And although the audience was probably the largest audience I’ve ever had, it felt empty.
The Talk
The talk went well. It started out rocky but once I got into the SQL, I got more comfortable. I had friends in the audience and I really appreciated their presence. The questions after were great. One lesson I’m taking for next time is to end maybe five or ten minutes early so I’m not in such a rush to get off the stage. There were many people who were waiting to ask me a question that never got a chance to.
It was a good experience and I want to do more of it. That means more practice. I’m double lucky because this week, I get to give the talk again for work! D2L is hosting an internal conference and I’m excited to deliver it to the home team.
For most of 2016, I worked with a small team of three called the Samurai team. The team name was taken from the wandering Samurai who wanders from village to village doing good where ever injustice was found. Our job was to go around doing good wherever technical debt was found.
And that was the point. It was wherever we found the technical debt. It was an exercise in trust I suppose. They trusted us to do what was important. We had more autonomy then I’ve ever enjoyed before. There was still accountability and everything we did was data-driven and pragmatic. But I really enjoyed the experience.
We did a lot of work and on the database scalability side, we focused on these things:
Avoiding queries
Tuning queries
Stabilizing execution plans
Concurrency
Database Concurrency
In 2016, more than ever before, I got to exercise my database concurrency skills in a real practical sense. It was cool to find out what rules of thumb were true and what rules of thumb didn’t matter.
Developing Highly Concurrent Databases
That’s why I’m really excited to talk about database concurrency at the PASS Summit. Developing Highly Concurrent Databases I’m here in Seattle this week and I get to deliver my talk called talk on Friday at 2PM.
But if you’re not in Seattle, you can choose to watch me on PASS TV! They’re live streaming one session room throughout the conference. And I’m fortunate enough to be presenting in that room.
If you’re here at PASS, mark your schedule for room 6E on Friday at 2PM (Pacific).
And if you’re not, you can still catch me and other presenters on PASStv (Friday at 5PM Eastern) http://www.sqlpass.org/summit/2016/Live.aspx.